Measures of central tendency / dispersion (std. Dev, var, IQR) + effect of constant changes to data: notes and practice questions
- Measures of Central Tendency:
- Mode: Most frequent value.
- Median (): Middle value of ordered data.
- Mean ( or ): Sum of data divided by number of data points.
- Measures of Dispersion:
- Quartiles (): Divide data into four equal sections.
- Range: Maximum value - Minimum value.
- Interquartile Range (IQR): .
- Variance (): Mean of squared differences from the mean.
- Standard Deviation (): Square root of variance; same units as data.
- Mean Formulas:
- Ungrouped data:
- Frequency table:
- Mid-interval value (for grouped data):
- Variance and Standard Deviation Formulas (GDC use expected):
- Variance:
- Standard Deviation:
- Comparing Data Sets:
- With outliers: Use median (central tendency) and IQR (dispersion).
- Symmetrical data: Use mean (central tendency) and standard deviation (dispersion).
- **Linear Transformations (Adding/Subtracting a constant ):**
- Mean:
- Standard Deviation, Variance, IQR, Range: Unchanged.
- **Linear Transformations (Multiplying by a constant ):**
- Mean:
- Standard Deviation:
- Variance:
- HL Formula Booklet (Expected Value & Variance):
- GDC Usage:
- Input data into statistics mode for quartiles, SD, variance.
- For grouped data, use mid-interval values as -values.
- Always check GDC output for logical consistency.
- Exam Pitfall: Adding/subtracting a constant does not change measures of dispersion (SD, variance, IQR, range).
- Grouped Data Estimates: Indicate estimates (e.g., by rounding to 3 s.f.) as values are not exact.
How it is examined
The quartile warning is worth taking seriously when marking: a hand-calculated quartile can legitimately differ from the GDC's, so a mark scheme should accept both unless the question forces one method. The constant-change results are a recurring two-mark question and are pure reasoning, no calculation. Estimating a mean from grouped data needs mid-interval values, and using the lower bound instead is the standard error.
The mean of a set of data, , where .
- Measures of central tendency: mean, median and mode.
- Estimation of the mean from grouped data.
- The modal class.
- Measures of dispersion: interquartile range, standard deviation and variance.
Linking questions
- Other contexts: comparing variation and spread in populations, human or natural, for example agricultural crop data, social indicators, reliability and maintenance.
- Links to other subjects: descriptive statistics (sciences, individuals and societies); the consumer price index (economics).
- International-mindedness: the benefits of sharing and analysing data from different countries; discussion of the different formulae for variance.
- TOK: could mathematics make alternative, equally true, formulae? What does that tell us about mathematical truths? Does the use of statistics lead to an over-emphasis on attributes that can be measured easily over those that cannot?
Practice questions
55 questions · 1 easy · 41 medium · 13 hardQuestion 1
EasyPaper 1 · calculator3 marksA tech company conducts tests on the battery life (in hours) of its new smartphone model. The results show that the battery life has a mean of hours and a standard deviation of hours.
Following a software update, every smartphone receives an additional hours of battery life. Write down the new mean battery life and the new standard deviation of the battery life.
Consider how adding a constant value to every data point affects the mean and the standard deviation of a dataset.
Question 2
MediumPaper 1 · calculator4 marksA group of ten students recorded the number of hours they spent studying for their final IB Mathematics exam in the week leading up to it.
Their results are shown below:
5, 7, 6, 8, 5, 9, 7, 6, 5, 10
For this data set, find the value of
(a) the mode.
A group of ten students recorded the number of hours they spent studying for their final IB Mathematics exam in the week leading up to it.
Their results are shown below:
5, 7, 6, 8, 5, 9, 7, 6, 5, 10
For this data set, find the value of
(b) the mean.
A group of ten students recorded the number of hours they spent studying for their final IB Mathematics exam in the week leading up to it.
Their results are shown below:
5, 7, 6, 8, 5, 9, 7, 6, 5, 10
For this data set, find the value of
(c) the standard deviation.
The mode is the value that appears most frequently in a data set.
To find the mean, sum all the values in the data set and divide by the total number of values.
You can use a GDC to calculate the standard deviation directly from the data set. Ensure you select the correct population or sample standard deviation based on the context (usually population for a given data set unless specified as a sample).
Question 3
HardPaper 1 · calculator11 marks(a) A botanist is studying a rare species of flower. They record the number of petals () on a sample of these flowers. The data is presented in the frequency table below:
5
6
7
8
9
10
Frequency
3
8
20
15
7
2
Find an unbiased estimate of the population mean number of petals for this rare flower species.
(b) Find an unbiased estimate of the population variance of the number of petals for this rare flower species.
(c) A botanist suspects that the average number of petals for this rare species is different from the average of 7.0 petals observed in a more common, related species. She sets up a hypothesis test with the null hypothesis .
(i) State the alternative hypothesis.
(ii) Given that all assumptions for this test are satisfied, carry out an appropriate hypothesis test. State and justify your conclusion, using a 10% significance level.
To find the unbiased estimate of the population mean, calculate the sum of (petal count × frequency) and divide by the total number of flowers in the sample.
Use your GDC to calculate the sample standard deviation () or variance () directly from the frequency table. Alternatively, calculate the sum of squared differences from the mean, weighted by frequency, and adjust for the unbiased estimate.
The botanist suspects the average is 'different from', which implies a two-tailed test.
Since the population standard deviation is unknown and you have sample data, a t-test is appropriate. Remember to use the unbiased estimate of the standard deviation and consider if it's a one-tailed or two-tailed test.
Question 4
MediumPaper 1 · calculator9 marksA software development company tracked the completion times of 150 projects. The cumulative frequency graph shows the completion times obtained by the projects.
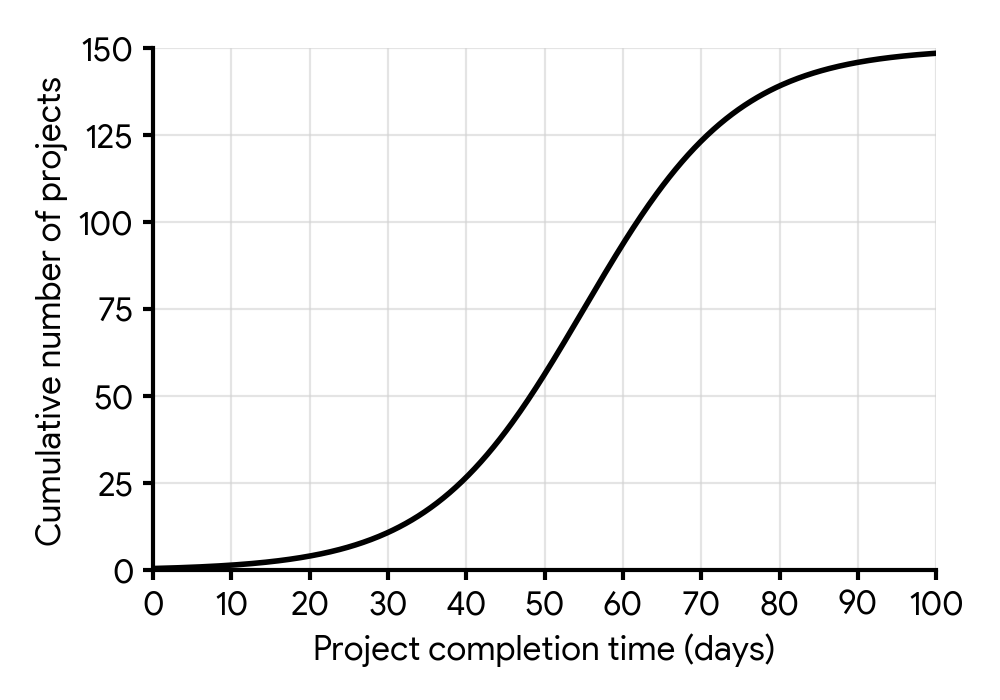
Find the median completion time of the projects.
The projects were assigned a performance tier from 1 to 5, depending on the completion time. The number of projects receiving each tier is shown in the following table.
| Tier | 1 | 2 | 3 | 4 | 5 |
|---|---|---|---|---|---|
| Number of projects | 8 | 15 | 30 | p | q |
Find an expression for in terms of .
The mean performance tier for these projects is 3.5.
Find the number of projects that obtained a tier 5.
Find the minimum completion time needed to obtain a tier 5.
The median is the value at the 50th percentile. For a cumulative frequency graph, this means finding the value on the x-axis that corresponds to half of the total frequency on the y-axis.
The total number of projects is 150. The sum of the number of projects in all tiers must equal the total number of projects.
Use the formula for the mean of a frequency distribution: . Substitute the expression for from part (b) into this formula and solve for .
If there are projects in Tier 5, then these are the projects with the longest completion times. To find the minimum time for Tier 5, you need to find the completion time corresponding to the th project on the cumulative frequency graph.
Question 5
HardPaper 2 · calculator12 marksThe following tables show the mean monthly rainfall, by month, in two different regions: Green Valley and Sunstone Coast.
Green Valley
Month | Mean monthly rainfall (mm)
---|---
January |
February |
March |
April |
May |
June |
July |
August |
September |
October |
November |
December |
Sunstone Coast
Month | Mean monthly rainfall (mm)
---|---
January |
February |
March |
April |
May |
June |
July |
August |
September |
October |
November |
December |
(a) Find the mean monthly rainfall over the course of the year for Green Valley.
(b) Find the standard deviation of the monthly rainfall in Green Valley.
(c) Find the mean monthly rainfall over the course of the year for Sunstone Coast.
(d) Find the standard deviation of the monthly rainfall in Sunstone Coast.
(e) By referring directly to your answers from parts (a) -(d), make contextual comparisons about the monthly rainfall in Green Valley and Sunstone Coast throughout the year.
To find the mean, sum all the monthly rainfall values and divide by the number of months.
Use your GDC to calculate the standard deviation. Ensure you input all 12 data points correctly.
Similar to part (a), sum the monthly rainfall for Sunstone Coast and divide by 12.
Use your GDC for this calculation, just like in part (b).
Compare the mean values to discuss overall rainfall amounts. Compare the standard deviation values to discuss the variability or consistency of rainfall.
Question 6
MediumPaper 1 · calculator5 marksA factory conducts quality control checks on the diameter (in mm) of components produced by Production Line A. A sample of measurements is recorded as:
18.2, 19.5, 20.1, 20.3, 20.5, 20.6, 20.8, 21.0, 21.2, 21.5, 22.0, 22.1, 22.3, 22.5, 23.0
For these data, the lower quartile is 20.3 mm and the upper quartile is 22.1 mm.
Show that a component with a diameter of 18.2 mm would not be considered an outlier.
Another production line, Line B, also produces similar components. The box and whisker diagram below displays the diameters (in mm) of a sample of components from Line B.
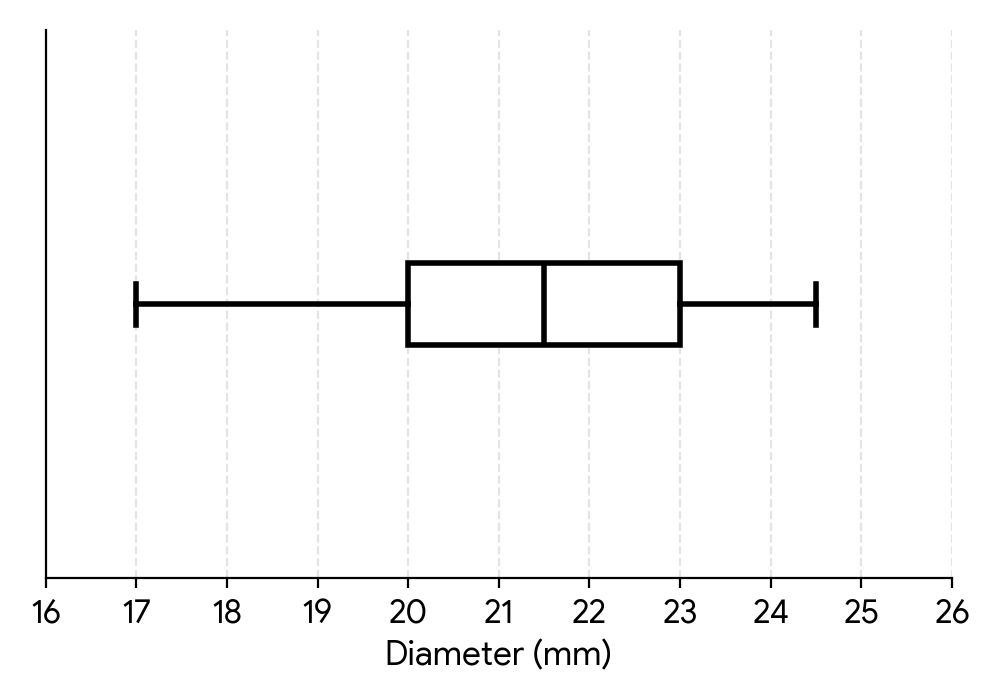
A quality control manager reviews the box and whisker diagrams for both lines and suggests that Production Line B generally produces components with larger diameters.
With reference to the box and whisker diagrams for Line A (from part (a) ) and Line B, state one aspect that may support the manager's opinion and one aspect that may counter it.
Recall the formula for identifying outliers using the interquartile range (IQR). An outlier is typically defined as a value that falls below or above .
Compare the key features of the box and whisker diagrams for Line A and Line B. Consider measures of central tendency (like median) and measures of spread (like IQR or range) to support or counter the manager's claim.
Question 7
HardPaper 2 · calculator22 marksA logistics company recorded the delivery times (in minutes) for a large batch of packages. The data is grouped in the frequency table below:
Delivery Time (minutes) | Frequency
---|---
|
|
|
|
|
|
|
|
|
|
(a) Calculate estimates of the mean and standard deviation of the delivery times.
(b) Construct a cumulative frequency table for the data, and use it to draw a cumulative frequency curve.
(c) Use your graph to estimate:
(i) the median delivery time
(ii) the lower and upper quartile of the delivery times
(iii) the interquartile range
(iv) the th percentile of delivery times.
(d) Draw a box-and-whisker plot of the data.
(e) Determine, with reasons, whether any customers could be considered outliers.
For grouped data, first find the midpoint of each class interval. Use these midpoints as the 'x' values for calculating the mean and standard deviation.
To construct the cumulative frequency table, add up the frequencies sequentially. When drawing the curve, plot the upper class boundary against the cumulative frequency.
The median corresponds to the 50th percentile. On the cumulative frequency curve, find the value on the x-axis that corresponds to 50% of the total frequency on the y-axis.
The lower quartile (Q1) is at 25% of the total frequency, and the upper quartile (Q3) is at 75% of the total frequency.
The interquartile range (IQR) is the difference between the upper quartile (Q3) and the lower quartile (Q1).
The 85th percentile corresponds to 85% of the total frequency.
Remember to include the minimum value, Q1, median, Q3, and maximum value. The whiskers extend to the minimum and maximum values that are not outliers.
Use the outlier rule: A data point is an outlier if it is less than or greater than . Consider the range of values within the extreme class intervals.
Question 8
MediumPaper 1 · calculator8 marksA group of 160 participants completed a fitness challenge. The cumulative frequency graph shows the points obtained by the participants.
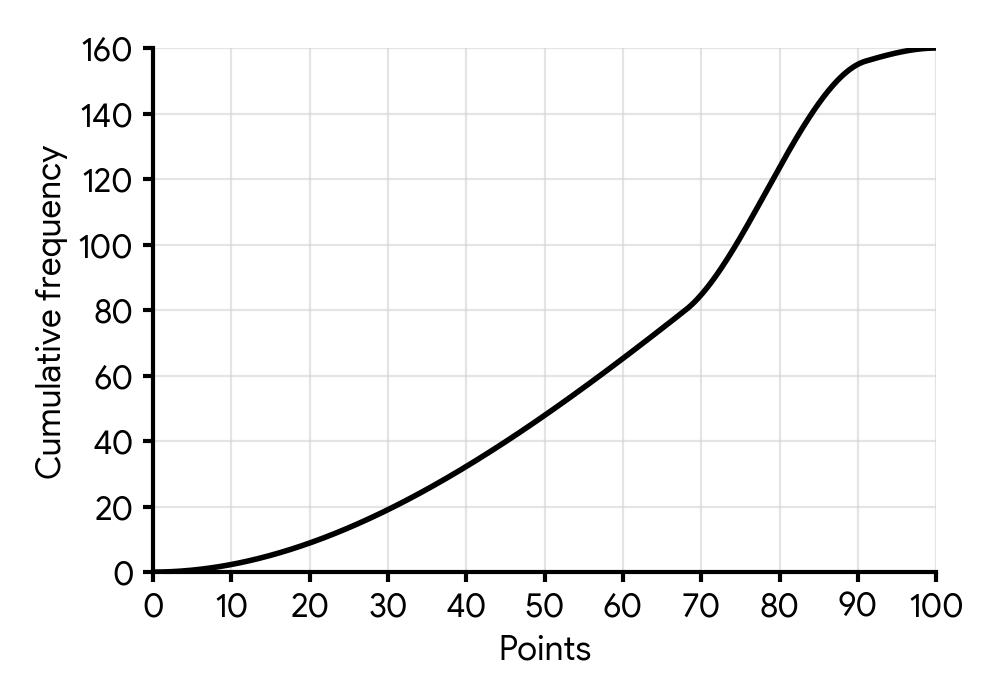
Find the median of the points obtained.
The participants were awarded a performance grade from 1 to 5, depending on the points obtained in the challenge.
The number of participants receiving each grade is shown in the following table.
| Grade | 1 | 2 | 3 | 4 | 5 |
|---|
| Number of participants | 8 | 15 | 30 | a | b |
|---|
Find an expression for in terms of .
The mean grade for these participants is 3.5.
Find the number of participants who obtained a grade 5.
Find the minimum points needed to obtain a grade 5.
The median corresponds to the value at the 50th percentile of the data. For 160 participants, this means finding the score for the 80th participant on the cumulative frequency graph.
The sum of all participants across all grades must equal the total number of participants in the fitness challenge.
The mean grade is calculated by summing the product of each grade and its frequency, then dividing by the total number of participants. Use the expression for 'a' from part (b).
Grade 5 represents the highest performance level. If 'b' participants obtained grade 5, these are the top 'b' participants. Use the cumulative frequency graph to find the score that separates the top 'b' participants from the rest.
Question 9
HardPaper 2 · calculator12 marksA survey was conducted to investigate the daily screen time (in minutes) of 80 students. The results are presented in the frequency table below.
Time ( minutes) | Frequency
---|---
|
|
|
|
|
|
|
(a) State the modal class.
(b) Find the class in which the median time lies.
(c) Construct a cumulative frequency table for this data.
(d) Sketch the cumulative frequency curve.
(e) Use your curve to find estimates for the median and interquartile range.
The modal class is the class interval with the highest frequency.
First, find the total number of students. The median position is half of the total number of students. Then, identify which class interval contains this position by summing frequencies.
For a cumulative frequency table, list the upper class boundaries and their corresponding cumulative frequencies. The cumulative frequency for a given class is the sum of its frequency and the frequencies of all preceding classes.
Plot the upper class boundaries against the cumulative frequencies. Remember to start the curve at the lower boundary of the first class with a cumulative frequency of 0.
To find the median, locate the cumulative frequency corresponding to half the total number of students. For the interquartile range, find the cumulative frequencies for the lower (25%) and upper (75%) quartiles. Then, read the corresponding time values from the x-axis.
Question 10
MediumPaper 1 · calculator19 marks[Maximum mark: 19]
A tech company recorded the time (in minutes) 180 customers spent completing a new online feedback survey. The data was compiled into the following cumulative frequency graph.
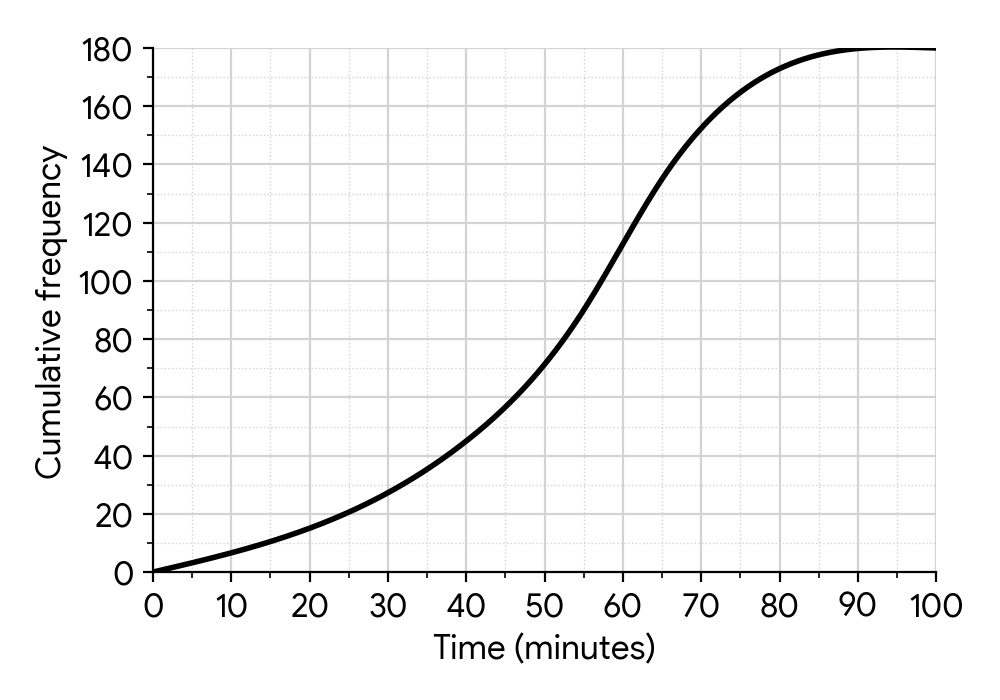
(a) Use the graph to find
(i) the median time;
(ii) the lower quartile;
(iii) the upper quartile;
(iv) the interquartile range.
Sarah completed the survey in 1.5 minutes.
(b) Determine whether Sarah's time is an outlier.
Remember to locate the correct cumulative frequency value for the median (50th percentile) before reading from the graph.
The lower quartile represents the 25th percentile of the data.
The upper quartile represents the 75th percentile of the data.
The interquartile range (IQR) is the difference between the upper quartile (Q3) and the lower quartile (Q1).
Recall the formula for identifying outliers: a data point is an outlier if it is less than Q1 - 1.5 IQR or greater than Q3 + 1.5 IQR.
Question 11
HardPaper 2 · calculator21 marksDr. Anya Sharma, a sports scientist, is investigating the relationship between training habits and performance in junior athletes. She wants to collect data on the weekly training hours of junior swimmers. She decides to interview every 5th swimmer entering the training facility until she has a sample of 50 swimmers.
State the sampling method Dr. Sharma has used.
Dr. Sharma constructed the following box and whisker diagram to show the weekly training hours (in hours) of a sample of junior swimmers.
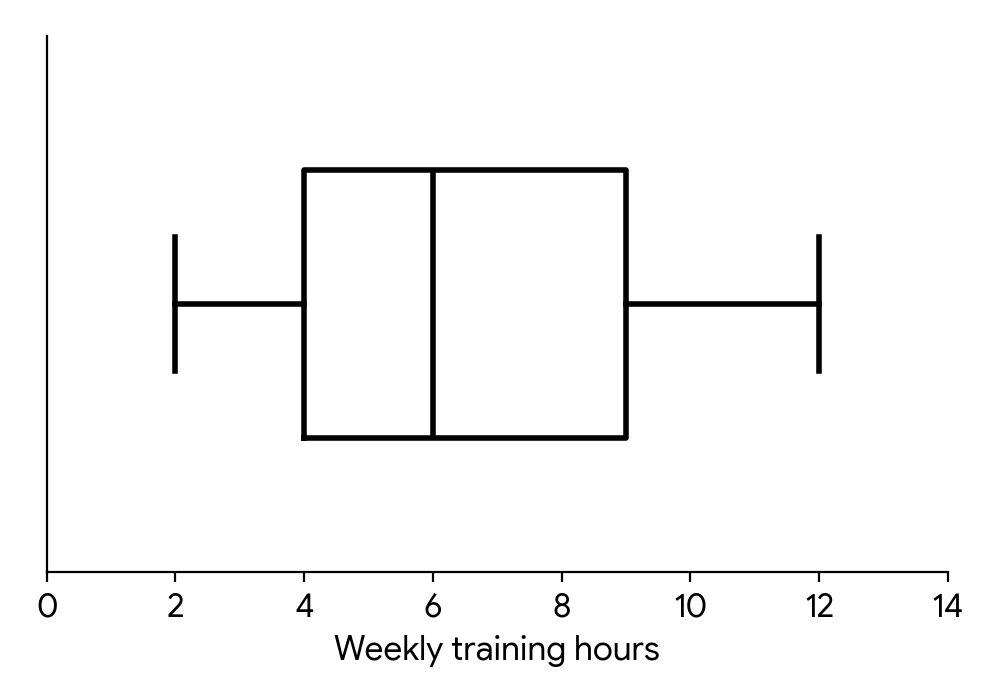
Write down the median weekly training hours.
Calculate the interquartile range for the weekly training hours.
One swimmer in the sample reported training for 15 hours per week. Dr. Sharma believes this swimmer's training time is not an outlier.
Determine whether Dr. Sharma is correct. Support your reasoning.
Dr. Sharma also collected data on the average weekly training hours () and the competition score () for a group of athletes. These data are represented on the scatter diagram.
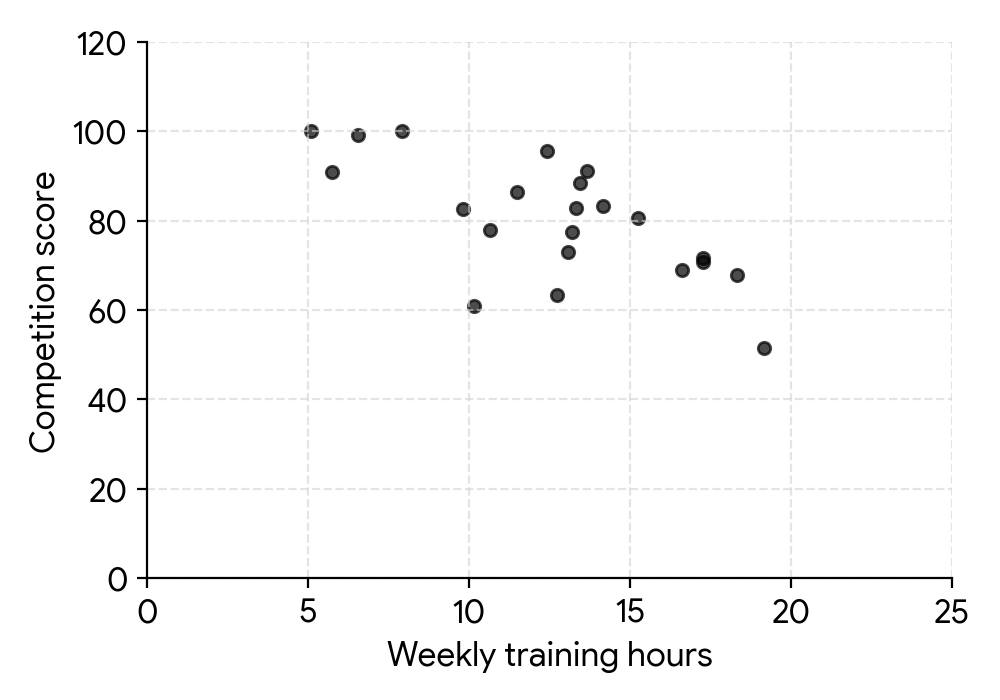
Describe the correlation between weekly training hours and competition score.
Dr. Sharma correctly calculates the equation of the regression line on for these athletes to be . She uses the equation to estimate the competition score for an athlete who trains 3 hours per week.
Find the competition score calculated by Dr. Sharma.
State whether it is valid to use the regression line on for Dr. Sharma's estimate in part (f). Give a reason for your answer, assuming the original data for training hours ranged from 5 to 20 hours.
Dr. Sharma investigated the relationship between an athlete's national competition rank and their average daily protein intake (in grams). She collected data for eight athletes, as shown in the table.
| Athlete | A | B | C | D | E | F | G | H |
|---|---|---|---|---|---|---|---|---|
| Competition Rank () | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 |
| Protein Intake (g) () | 180 | 150 | 200 | 160 | 140 | 190 | 170 | 130 |
Dr. Sharma intends to analyse the data using Spearman's rank correlation coefficient, .
Copy and complete the information in the following table.
| Athlete | A | B | C | D | E | F | G | H |
|---|---|---|---|---|---|---|---|---|
| Rank - Competition Rank | 1 | |||||||
| Rank - Protein Intake |
Calculate the value of .
Interpret your result.
Consider how the sample is selected. Is there a systematic rule applied, or is it based on categories and targets?
The median is represented by the line inside the box of a box and whisker diagram.
The interquartile range (IQR) is the difference between the third quartile (Q3) and the first quartile (Q1).
An outlier is typically defined as a data point that falls more than 1.5 times the interquartile range (IQR) below the first quartile (Q1) or above the third quartile (Q3). Calculate the upper and lower fences.
Observe the general trend of the points on the scatter diagram. Do they tend to go up or down from left to right?
Substitute the given value of into the regression equation to find the corresponding value.
Consider if the value used for prediction falls within the range of the original data used to create the regression line.
Assign ranks to the 'Protein Intake' values. If 'Competition Rank' is already ranked from 1 to 8 (best to worst), then for 'Protein Intake', assign rank 1 to the highest intake, rank 2 to the next highest, and so on.
Use the formula for Spearman's rank correlation coefficient: , where is the difference between the ranks and is the number of data pairs.
Consider the sign and magnitude of . What does a positive or negative value mean, and what does a value close to 0 or 1 (or -1) indicate about the strength of the relationship?
Question 12
MediumPaper 1 · calculator4 marks[Maximum mark: 4]
A salesperson records the number of items sold per day over several weeks. The data is presented in the following frequency distribution table.
| Number of items sold () | Frequency () |
|---|---|
| 1 | 3 |
| 2 | 5 |
| 3 | 8 |
| 4 | p |
| 5 | 6 |
| 6 | 4 |
| Frequency (f)
------------------------|---------------
1 | 3
2 | 5
3 | 8
4 | p
5 | 6
6 | 4
)
For this distribution, the mean number of items sold per day is 3.8.
(a) Write down the total number of days the salesperson recorded data in terms of p.
(b) Calculate the value of p.
To find the total number of days, sum all the frequencies in the table.
The formula for the mean of a frequency distribution is . Use the given mean and your expression for the total number of days from part (a).
Question 13
HardPaper 2 · calculator15 marksA quality control manager at a manufacturing plant wants to assess the consistency of a new batch of electronic components. He decides to test ten components, ensuring that five are selected from Production Line A and five from Production Line B. The manager instructs the supervisors of each line to provide the required number of components from their current production.
(a) Name the type of sampling that best describes the method used by the quality control manager.
The weights, in grams, of the ten components selected for the test are:
.
(b) For these ten components, find
(i) the mean weight.
(ii) the standard deviation of the weights.
The target weight for these components is g. The manager is concerned that the components might be consistently underweight. Perform an appropriate test at the significance level to see if the mean weight of the components produced is less than the target weight. It can be assumed that the weights come from a normal population.
State one reason why the test performed in part (c) might not be valid.
Two additional components are tested at a later date. The mean weight for all twelve components is g and the standard deviation is g.
For further analysis, a 'quality score' for the twelve components is obtained by multiplying the weights by and subtracting .
(e) For the twelve components, find
(i) their mean quality score.
(ii) the standard deviation of their quality score.
Consider how the sample is structured based on characteristics (like production line) and how the specific units are chosen within those structures.
To find the mean, sum all the weights and divide by the number of components.
Use a GDC for efficient calculation of standard deviation. Ensure you are using the sample standard deviation if the context implies the sample is used to estimate a population, or population standard deviation if the sample is the entire population of interest.
Formulate null and alternative hypotheses. Since the population standard deviation is unknown and the sample size is small, a t-test is appropriate. Use your GDC to find the p-value and then compare it to the significance level.
Consider the method used to select the components for testing and whether it truly represents the entire production.
When data is transformed linearly by , the new mean is .
When data is transformed linearly by , the new standard deviation is .
Question 14
MediumPaper 1 · calculator7 marksA tech company launched two new smartphone models, "Voyager" and "Explorer". They collected customer satisfaction scores (out of 100) from a large sample of users for both models. The results are summarized in the following box and whisker diagram.
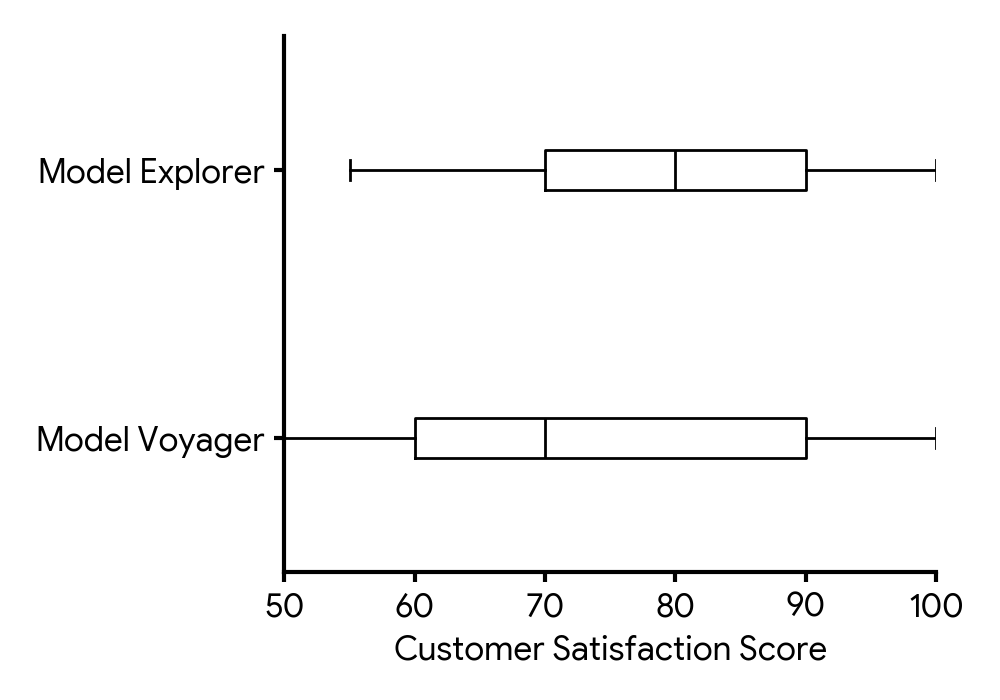
Identify which two of the following statements must be true according to the box and whisker diagram. Indicate your choices by placing tick marks in the second column of the following table.
Statement | True (✓)
---|---
The satisfaction scores for Model Voyager are normally distributed. |
A higher percentage of customers gave a score less than 70 for Model Voyager than for Model Explorer. |
A higher percentage of customers gave a score greater than 90 for Model Explorer than for Model Voyager. |
The interquartile range for Model Explorer is less than the interquartile range for Model Voyager. |
A product manager believes there is no significant difference in the average customer satisfaction scores between the two models. She plans to conduct a t-test at the 10% significance level. Write down the null and alternative hypotheses for her test.
The t-test yielded a p-value of 0.0783. Find the p-value for her test.
Write down the conclusion to the test. Give a reason for your answer.
Recall how percentages of data are distributed within the quartiles of a box and whisker diagram. For example, 25% of data lies below the first quartile (Q1), and 50% lies below the median. The interquartile range (IQR) is the difference between the third quartile (Q3) and the first quartile (Q1).
Remember that the null hypothesis (H₀) typically states no effect or no difference, while the alternative hypothesis (H₁) states what is being tested for (a difference). Use appropriate notation for population means.
The p-value is directly provided in the question stem.
Compare the p-value from part (c) with the significance level stated in part (b) to determine whether to reject the null hypothesis.
Question 15
HardPaper 2 · calculator21 marksThe lifespans, , of 250 LED light bulbs are recorded in the following table.
| Lifespan (hours) | Frequency |
|---|---|
| 20 | |
| 60 | |
| 90 | |
| 55 | |
| 25 |
This table is used to create a cumulative frequency graph.
Write down the mid-interval value of the class .
Calculate an estimate of the mean lifespan of the 250 light bulbs.
Use the cumulative frequency curve (which would be provided in an exam) to estimate the interquartile range. Assume the lower quartile () is hours and the upper quartile () is hours.
A light bulb from the data set had a lifespan of hours.
Use your answer to part (b) to estimate whether this light bulb's lifespan is an outlier for this data. Justify your answer.
It is believed that the lifespans of these LED light bulbs follow a normal distribution with mean hours and standard deviation hours.
It is decided to perform a goodness of fit test on the data to determine whether this sample of 250 light bulbs could have plausibly been drawn from an underlying distribution .
Write down the null and the alternative hypotheses for the test.
As part of the test, the following table is created.
| Lifespan of light bulb (hours) | Observed frequency | Expected frequency |
|---|---|---|
| 20 | 14.0 | |
| 60 | 60.1 | |
| 90 | a | |
| 55 | 60.1 | |
| 25 | b |
Find the value of and the value of . Give your answers to one decimal place.
Hence, perform the test to a 5% significance level, clearly stating the conclusion in context.
The mid-interval value is the average of the lower and upper bounds of the class interval.
To estimate the mean from grouped data, multiply each mid-interval value by its corresponding frequency, sum these products, and then divide by the total frequency.
The interquartile range (IQR) is the difference between the upper quartile () and the lower quartile ().
An outlier is typically defined as a value that is more than below or above . Calculate the upper bound for outliers.
The null hypothesis () usually states that there is no difference or that the data fits the proposed model. The alternative hypothesis () states that there is a difference or the data does not fit the model.
For a normal distribution , the probability can be found using the cumulative distribution function (CDF), . Then, multiply this probability by the total number of observations to get the expected frequency.
Calculate the Chi-squared test statistic using the formula . Then find the p-value using the degrees of freedom (). Compare the p-value to the significance level to draw a conclusion.
Question 16
MediumPaper 1 · calculator7 marksA logistics company recorded the weights, in kilograms (kg), of six parcels dispatched in a single hour:
1.25 kg, 1.80 kg, 1.50 kg, 1.25 kg, 2.10 kg, 1.60 kg
For these six parcels, find
(i) the mean weight.
(ii) the median weight.
(iii) the modal weight.
(iv) the range of the weights.
A new parcel is added to the shipment. Its weight is measured as 1.75 kg to the nearest 10 grams.
Write down the shortest possible weight of this new parcel.
To find the mean, sum all the weights and divide by the number of parcels.
First, arrange the weights in ascending order. The median is the middle value. If there are two middle values, average them.
The mode is the value that appears most frequently in the dataset.
The range is the difference between the highest and lowest values in the dataset.
Remember that 10 grams is equivalent to 0.01 kg. When a measurement is given to the nearest unit, the actual value lies within half of that unit above or below the stated measurement.
Question 17
HardPaper 2 · calculator21 marksA company manufactures specialized medical devices. Each device consists of a main circuit board and a protective casing. The weight of the circuit board, , is normally distributed with a mean of g and a standard deviation of g. The weight of the protective casing, , is normally distributed with a mean of g and a standard deviation of g. The weights of the circuit board and the casing are independent.
Find the probability that a randomly chosen complete device has a total weight of less than g.
A batch of such devices is to be packed into a container. The container has a maximum weight capacity of g. The weight of each device is independent.
Find the probability that the total weight of the devices is greater than the capacity of the container.
The company sources a critical microchip component from two different suppliers, Supplier X and Supplier Y. An engineer claims that microchips from Supplier Y have a lower response time than those from Supplier X. To test this claim, a random sample is taken from each supplier.
The eight microchips in the sample from Supplier X have response times, in milliseconds (ms), of:
.
Find the
(i) mean response time for the sample from Supplier X.
Find the
(ii) unbiased estimate of the population variance for the sample from Supplier X.
The seven microchips in the sample from Supplier Y have a mean response time of ms and an unbiased estimate of the population standard deviation () of ms.
Perform a suitable test, at the significance level, to test the engineer's claim that microchips from Supplier Y have a lower response time than those from Supplier X. You may assume the response times of microchips from each supplier are normally distributed with equal population variance.
The total weight of the device is the sum of the circuit board weight and the casing weight. When combining independent normal random variables, their means add, and their variances add. Remember that the standard deviation is the square root of the variance. Once you have the mean and standard deviation of the total weight, you can use the normal distribution to find the required probability.
Let be the total weight of the devices. Since each device's weight is normally distributed and independent, the sum of such weights will also be normally distributed. The mean of the sum will be times the mean of a single device, and the variance of the sum will be times the variance of a single device. Use the mean and variance calculated in part (a).
To find the mean of a sample, sum all the values in the sample and divide by the number of values in the sample.
The unbiased estimate of the population variance, , is calculated using the formula , where is the sample size and is the sample mean. Be careful to use in the denominator.
This is a hypothesis test comparing the means of two independent samples. Since the population standard deviations are unknown but assumed equal, and the samples are from normally distributed populations, a two-sample t-test (pooled variance) is appropriate. Remember to state the null and alternative hypotheses, calculate the test statistic and p-value, and draw a conclusion in context based on the significance level.
Question 18
MediumPaper 1 · calculator6 marks(a) The formula for converting daily steps, , to a fitness score, , is given by .
(i) Find a formula for converting a fitness score, , back to daily steps, .
(ii) A user achieved a fitness score of 75. Calculate the number of daily steps they took.
(b) Over a month, the mean daily steps recorded by a group of users was 8500 steps with a standard deviation of 1200 steps.
For the same group, find
(i) the mean daily fitness score.
(ii) the standard deviation of the daily fitness scores.
To find the inverse formula, you need to rearrange the given equation to make the subject.
Substitute the given fitness score into the formula you found in part (a)(i).
When a dataset is transformed by , the new mean is .
When a dataset is transformed by , the new standard deviation is . The constant does not affect the standard deviation.
Question 19
HardPaper 2 · calculator21 marks(a) The scores, , of 200 students on a mathematics test are recorded in the following table.
| Score () | Frequency |
|---|---|
| 15 | |
| 35 | |
| 60 | |
| 50 | |
| 30 | |
| 10 |
(i) Write down the mid-interval value of .
(ii) Calculate an estimate of the mean score of the 200 students.
(b) The data from this table is used to create a cumulative frequency graph. From this graph, the first quartile () is estimated to be and the third quartile () is estimated to be .
Use these values to estimate the interquartile range (IQR).
(c) A student, Elara, scored on the test.
Use your answer to part (b) to estimate whether Elara's score is an outlier for this data. Justify your answer.
(d) It is believed that the scores of students on this mathematics test follow a normal distribution with mean and standard deviation .
It is decided to perform a goodness of fit test on the data to determine whether this sample of 200 students could have plausibly been drawn from an underlying distribution .
Write down the null and the alternative hypotheses for the test.
(e) As part of the test, the following table is created, where some categories have been combined to ensure expected frequencies are not too low.
| Score () | Observed Frequency | Expected Frequency |
|---|---|---|
| 15 | 6.08 | |
| 35 | 32.08 | |
| 60 | a | |
| 50 | 63.99 | |
| 40 | b |
(i) Find the value of and the value of .
(ii) Hence, perform the test to a 5% significance level, clearly stating the conclusion in context.
The mid-interval value is the average of the lower and upper bounds of the interval.
To estimate the mean from grouped data, multiply each mid-interval value by its frequency, sum these products, and then divide by the total number of students.
The interquartile range (IQR) is the difference between the third quartile () and the first quartile ().
An outlier is typically defined as a value that is more than below or above . Calculate the upper and lower bounds for outliers.
The null hypothesis () states that there is no significant difference, while the alternative hypothesis () states that there is a significant difference. Make sure to reference the specific distribution parameters.
(i) Use the normal distribution to calculate the probabilities for the given intervals and multiply by the total number of students (200) to find the expected frequencies.
(ii) Calculate the statistic and the p-value. The degrees of freedom for a goodness-of-fit test when parameters are given is (number of categories - 1). Compare the p-value to the significance level to draw a conclusion.
Question 20
MediumPaper 1 · calculator9 marks(a) A quality control inspector at a beverage company takes a random sample of eight bottles of orange juice from a production line. The measured volumes, in ml, are:
298.5, 301.2, 299.1, 300.8, 298.9, 301.5, 299.7, 300.3
(i) Find an unbiased estimate for the mean volume of orange juice in a bottle from this production line.
(ii) Calculate a 95% confidence interval for the population mean volume. Give your answer to four significant figures.
(b) State one assumption you have made in order for your interval to be valid.
(c) The label on each bottle states: "Volume: 300 ml".
Using your answer to part (a)(ii), briefly comment on the claim on the label.
To find an unbiased estimate for the population mean, you should calculate the sample mean of the given data.
You will need to calculate the sample standard deviation (unbiased estimate) and use the t-distribution for the confidence interval, as the population standard deviation is unknown and the sample size is small.
Consider the underlying distribution of the data when constructing a t-interval for the mean.
Check if the claimed value falls within the calculated confidence interval. What does this imply about the claim?
No question on this page matches those filters. Try another difficulty or paper.
35 more Measures of central tendency / dispersion (std. Dev, var, IQR) + effect of constant changes to data questions in the app
Every answer is marked mark by mark, IB-style, and the AI tutor helps when you are stuck.
Where marks are lost
- Using your own wrong value after failing a "show that." All follow through is withdrawn for the rest of that question.
- Leaving an answer in calculator notation. Never accepted in a final answer, and AI's constant calculator use makes this the easiest slip in the whole subject.